
Introduction
Medical AI models do not perform uniformly across clinical domains. Each model exhibits distinct strengths depending on the specialty area, task type, and underlying medical complexity.
This page compiles a comprehensive view of model performance across medical tasks, body systems, and question types, based on Sully’s benchmarking of leading LLMs.
Why domain level variation exists
Even state-of-the-art models show substantial variability across specialties due to differences in:
Depth of domain-specific medical knowledge
Requirements for multi-step reasoning vs. factual recall
Model design (generalist vs. domain-trained)
Variances in training corpora and clinical content familiarity
Performance
By medical task (Diagnosis, treatment, basic science)
Benchmarks reveal significant differences across task types:
Diagnosis: Best handled by O1 and O3-MINI
Treatment: GPT-4.5-PREVIEW shows specialty strength
Basic Science: Few models exceed 30% accuracy; tasks remain the hardest

By body system
Model strengths diverge sharply depending on the clinical system involved.
Examples:
Lymphatic: O3-MINI reaches 62.5% (top model result)
Digestive: O1 peaks at 59.09% (best system for O1)
Endocrine: GPT-4.5-PREVIEW achieves 53.85%
Respiratory: O3-MINI at 42.9%

Standout specialty-specific wins
Some combinations reach exceptional accuracy (>90th percentile)

This illustrates how specialist-focused models or ensembles can outperform generalized models in meaningful clinical niches.
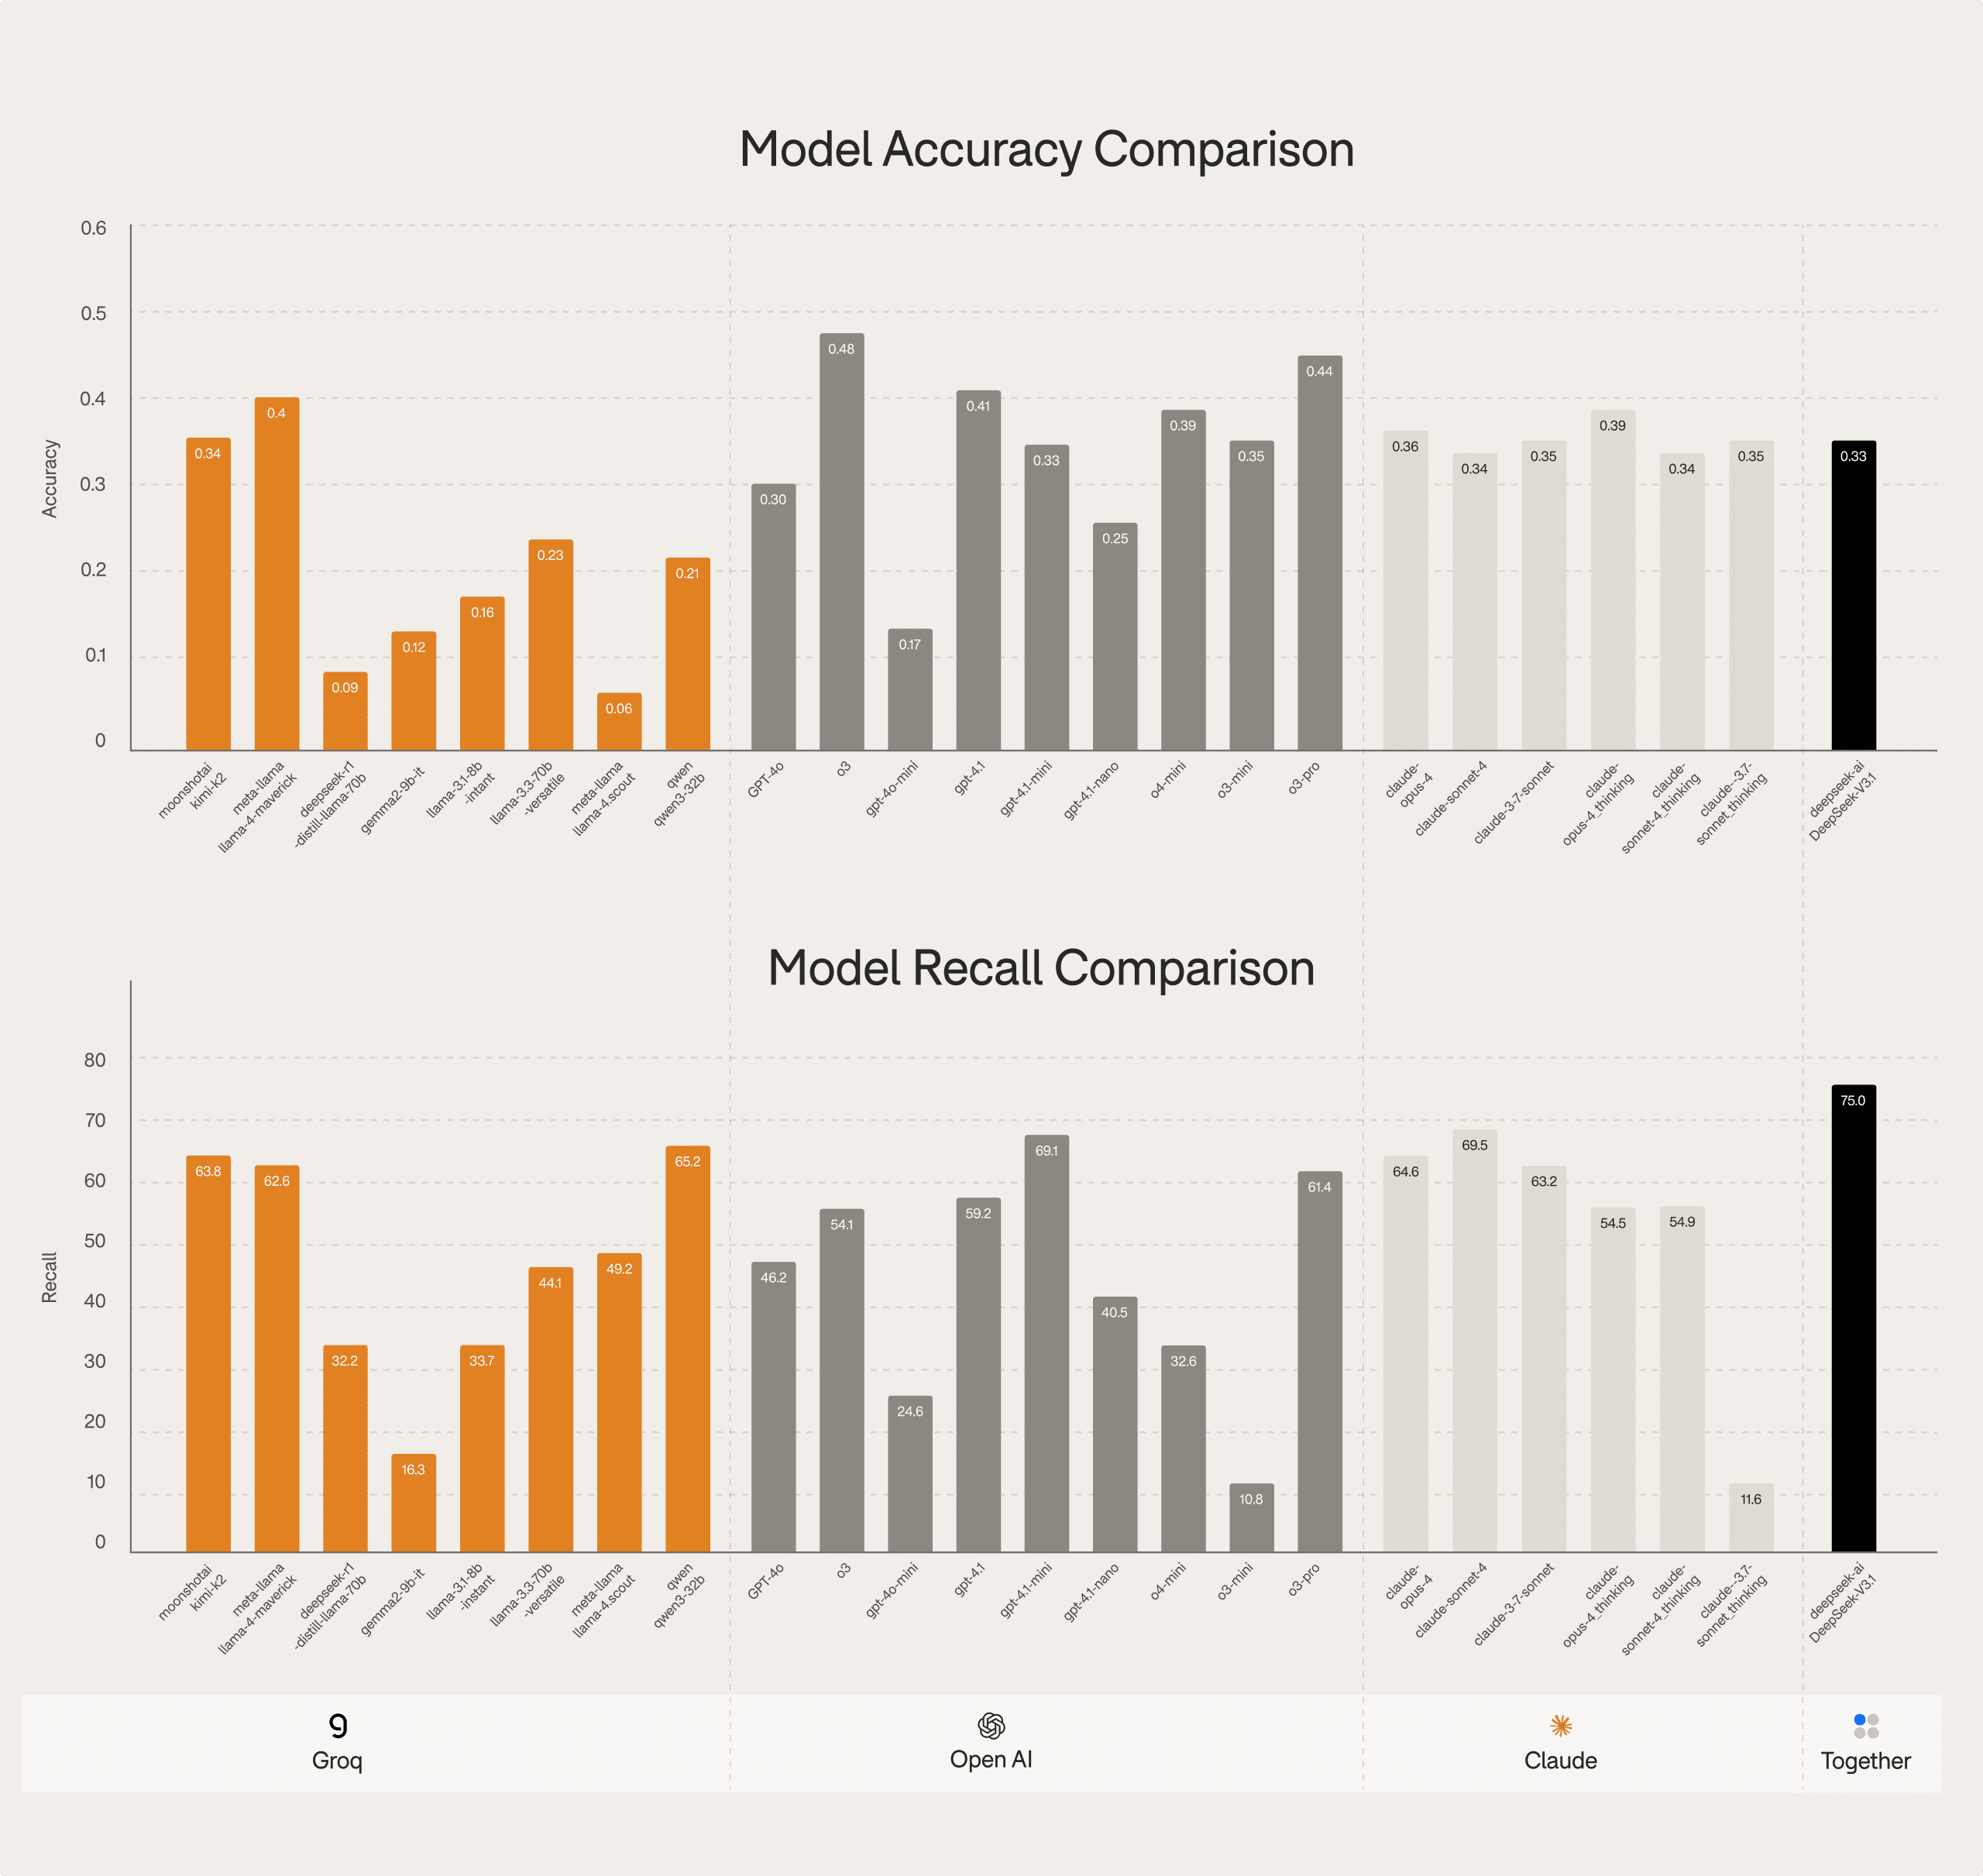
Cross-vendor comparison
Groq models show competitive recall
OpenAI models demonstrate strong accuracy in higher-tier models
Claude models display consistent but mid-range performance
Together (Deepseek-distill) peaks well in recall in limited contexts
Key takeaways
No model is universally strong specialty strengths vary widely.
Consensus ensembles outperform single models in specialized.
Basic science knowledge is a shared weakness across models.
Confidence is not equal to accuracy calibration is still a major challenge.
Vendor performance varies leaving major clinical
← Explore our other research